
Cooperative Multi-Agent Vision-Language-Action Models via Reinforced Fine-Tuning
Published in International Conference on Learning Representations (ICLR 2027), under review, 2026
Under review at the International Conference on Learning Representations (ICLR 2027). Preprint: arXiv:2609.36588
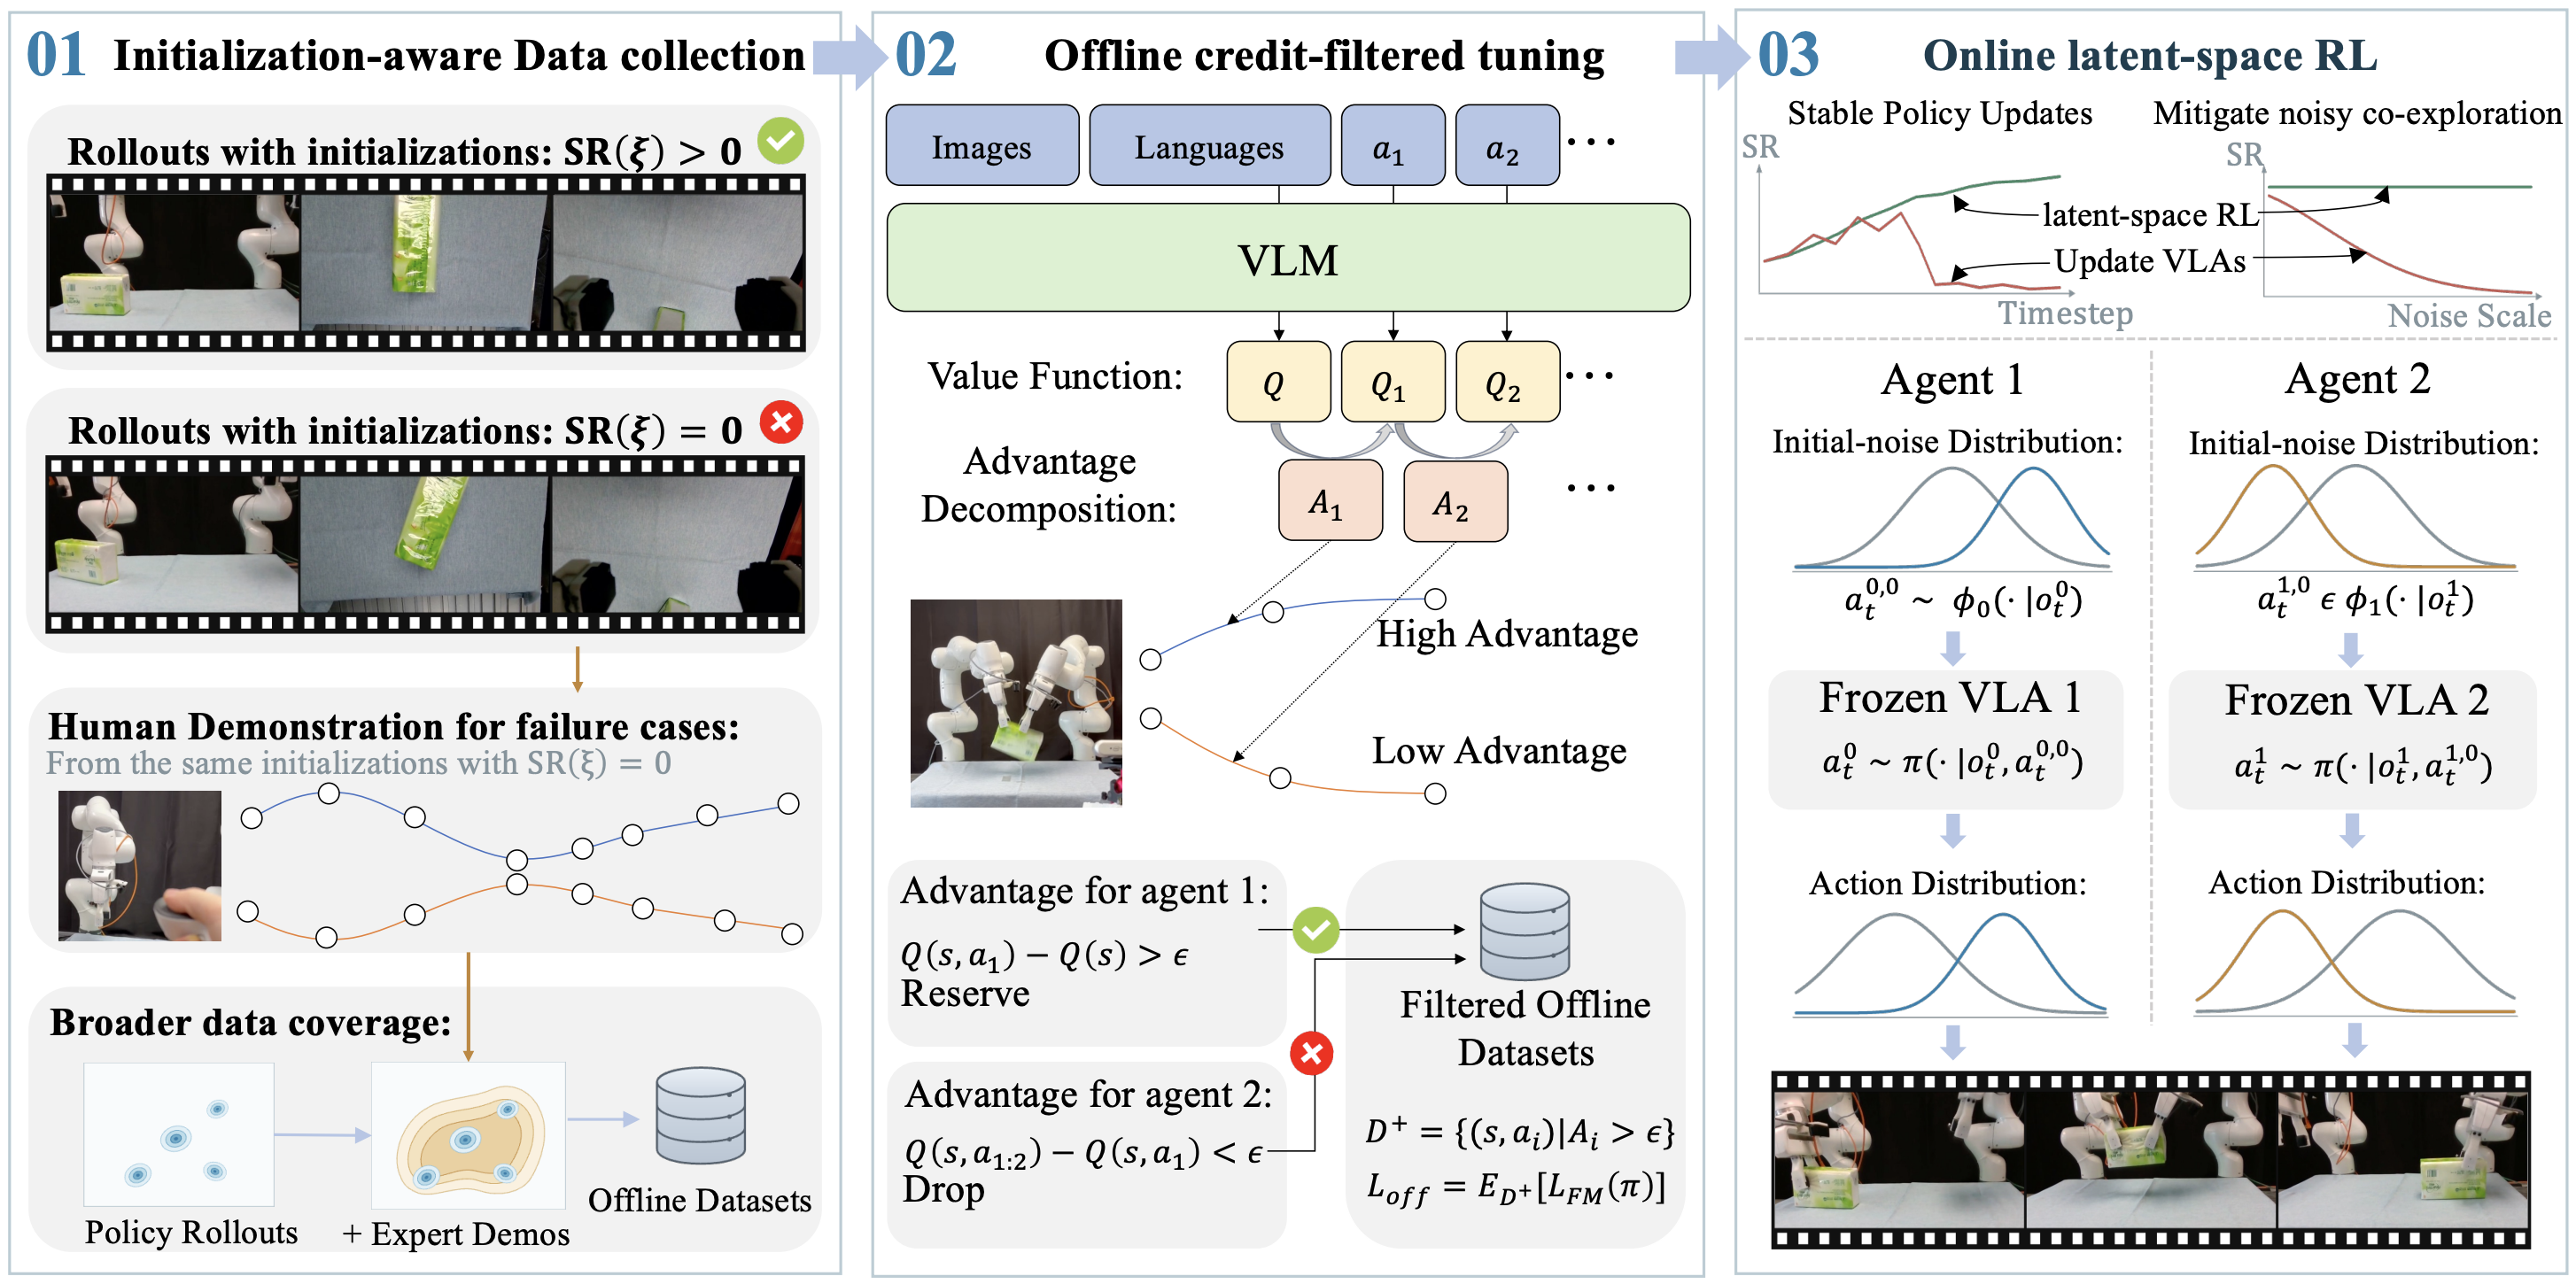
The paper studies reinforced fine-tuning for cooperative multi-agent vision-language-action models. The pipeline has three stages: initialization-aware data collection, offline credit-filtered tuning, and online latent-space reinforcement learning. It is evaluated with π₀ and π₀.₅ on RoboTwin, RoboFactory, and real-world manipulation with two Franka robots.
BibTeX Citation
@misc{xu2026cooperative,
  title={Cooperative Multi-Agent Vision-Language-Action Models via Reinforced Fine-Tuning},
  author={Xu, Ruixiao and Wong, Lik Hang Kenny and Liu, Zhiqian and Guo, Jianing and Li, Hanxiao and Shi, Kejian and Zhang, Shuning and Feng, Pu and Ma, Yongjia and Ma, Yuqing and Chen, Kai and Dou, Qi and Yang, Yaodong and Liu, Xianglong and Li, Simin},
  year={2026},
  eprint={2609.36588},
  archivePrefix={arXiv},
  primaryClass={cs.RO},
  url={https://arxiv.org/abs/2609.36588},
  note={Under review at ICLR 2027}
}